AI Verification: How We Actually Know an AI System Can Be Trusted
As AI systems take on higher-stakes roles, in healthcare, finance, infrastructure, and defence, a hard question keeps surfacing: how do we actually know an AI model does what it claims, was trained on legitimate data, and hasn’t been tampered with since deployment? This isn’t a philosophical concern. It’s an active, well-funded area of technical research with real methods and real limitations.
Why Verification Has Become Urgent
AI capabilities have advanced to the point where the stakes of getting verification wrong are genuinely high. In early 2026, Anthropic chose not to publicly release its most advanced model at the time due to safety concerns, reporting that internal testing had found thousands of high-severity vulnerabilities across major operating systems and browsers. Decisions about which models get released, and to whom, are becoming higher-stakes by the month, which is exactly why verifying what a model can actually do, before and after deployment, matters.
The Two Core Questions Verification Tries to Answer
At a basic level, AI verification is trying to answer two things: is a specific system actually using an AI model at all, and if so, what is that model capable of doing or affecting? Answering both reliably closes off a wide range of ways AI can be misused or misrepresented.
Zero-Knowledge Machine Learning (ZKML)
One of the more promising cryptographic approaches is zero-knowledge machine learning. A prover runs a model and generates a cryptographic proof that a specific inference followed a specific, committed set of weights and produced a specific output, without revealing the weights or the input itself. A verifier can confirm the claim is true without ever seeing the underlying model or data. This is particularly relevant in finance and healthcare, where an institution needs to prove a model ran correctly on protected data without exposing patient records or trading information.
The Real Cost of Cryptographic Verification
ZKML isn’t free. Generating a cryptographic proof for a single inference can cost significantly more compute than running that inference in the first place, which currently limits proving to cases where the assurance is genuinely worth the overhead, high-stakes financial or medical decisions, rather than everyday consumer AI interactions.
Confidential Computing and Hardware-Level Trust
A separate approach relies on confidential computing: hardware environments designed so that even the infrastructure operator cannot inspect what’s running inside a secure enclave. Combined with cryptographic attestation, this lets a third party confirm a specific model is running, with specific safeguards active, without needing direct access to the underlying weights.
Formal Verification: Mathematical Proof of Behaviour
Formal verification uses mathematical techniques to prove that a system behaves according to a specific, precisely defined specification, rather than simply testing it against sample cases. A 2026 RAND survey of 23 experts across formal methods, AI infrastructure, cybersecurity, and hardware architecture examined which parts of the machine learning stack are realistically amenable to this kind of proof, and concluded that hardware vendors publishing verifiable interfaces for instruction set architectures would meaningfully help close current gaps.
Formal Verification’s Practical Limits
Formal methods currently work best for checking specific, narrow properties, such as how a model’s output changes given small changes to its input, which is useful for verifying robustness but does not amount to a full guarantee of a model’s overall behaviour across every possible scenario.
Explainability Audits
Explainability techniques such as SHAP and LIME attempt to show which specific inputs most influenced a given model decision, giving auditors a way to check whether a decision was based on reasonable factors or something that shouldn’t have mattered. These tools have become a standard part of AI testing checklists, alongside logging verification, which confirms a model’s decisions and confidence levels are properly recorded for later audit. This same scrutiny is worth applying to everyday AI use too, including learning to fact-check AI chatbot answers before relying on them.
Training Data Verification: The “Garbage In, Garbage Out” Problem
Even a perfectly verified model is only as trustworthy as the data it learned from. A frequently cited real-world example: Amazon built a resume-screening model trained on the company’s own historical hiring data. It successfully learned exactly the pattern present in that data, and because most of the highly-rated resumes in the training set happened to belong to men, the model learned to penalise resumes associated with women, without anyone ever explicitly telling it to. The model wasn’t malfunctioning; it was accurately reflecting a biased dataset. This is why data lineage and consent verification, confirming training data was collected and labelled appropriately, has become as important as verifying the model itself.
Regulatory Verification Requirements
The EU AI Act requires high-risk AI systems to implement formal risk management, data governance, transparency, and human oversight, giving legal weight to verification practices that were previously optional best practice. Compliance checklists increasingly reference frameworks like GDPR and HIPAA alongside AI-specific requirements, particularly for systems used in healthcare, finance, and public infrastructure.
Copyright and Output Verification
A newer category of verification checks whether a generative model’s output reproduces copyrighted training material verbatim, an increasingly important check as generative AI systems are deployed in content-facing products where accidental verbatim reproduction carries real legal risk.
Why No Single Method Is Enough
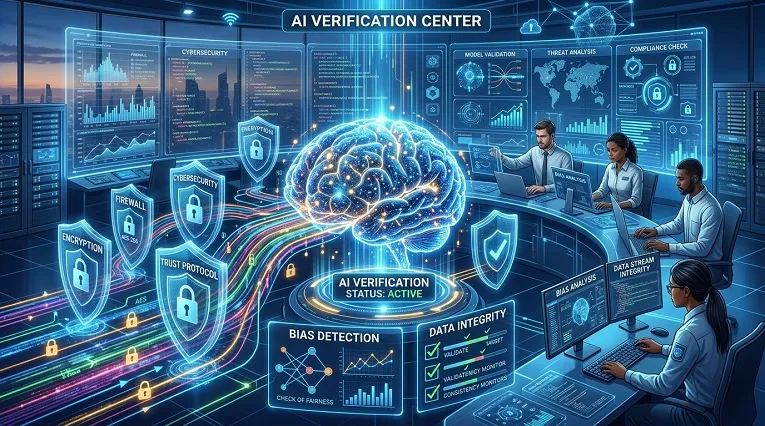
Researchers at a 2026 workshop co-hosted by FAR.AI and the Center for AI Safety, bringing together over 100 researchers examining how third parties can verify AI systems without full access to their internals, concluded that meaningful assurance will likely require combining multiple approaches, hardware, cryptography, formal methods, and external measurement, each covering different failure modes, rather than relying on any single technique.
What This Means in Practice
- High-stakes AI deployments increasingly combine several verification layers rather than relying on one method alone
- Cryptographic and formal verification remain expensive and are currently reserved for the highest-stakes use cases
- Training data quality and bias checks matter as much as verifying the model’s technical behaviour
- Regulatory frameworks like the EU AI Act are turning previously optional verification practices into legal requirements for high-risk systems
Frequently Asked Questions
Can AI verification completely eliminate the risk of a biased or unsafe model?
No single method guarantees this. Combining data verification, output testing, and ongoing monitoring significantly reduces risk, but researchers in the field are explicit that full assurance remains a genuinely unsolved problem for the most complex AI systems.
Is AI verification only relevant for large enterprises and governments?
The most expensive cryptographic and formal methods are currently concentrated in high-stakes finance, healthcare, and infrastructure use cases, but lighter-weight practices like explainability audits and data lineage checks are increasingly relevant for any business deploying AI in a customer-facing product.
Conclusion
AI verification has moved from a theoretical concern to an active engineering discipline, spanning cryptography, formal mathematics, hardware design, and data governance. No single technique currently provides complete assurance, which is exactly why researchers increasingly favour layering multiple verification methods rather than trusting any one approach alone.
About the Author